


来源:中国图像图形协会CSIG
原文链接:https://mp.weixin.qq.com/s/NsxmyhW5hrRs8anJVSLI1A
近日,ACM MM 2026论文录用结果公布,中国图像图形学会会员多篇论文被录用。今天为大家带来其中9篇论文介绍,后续将持续更新,敬请关注~


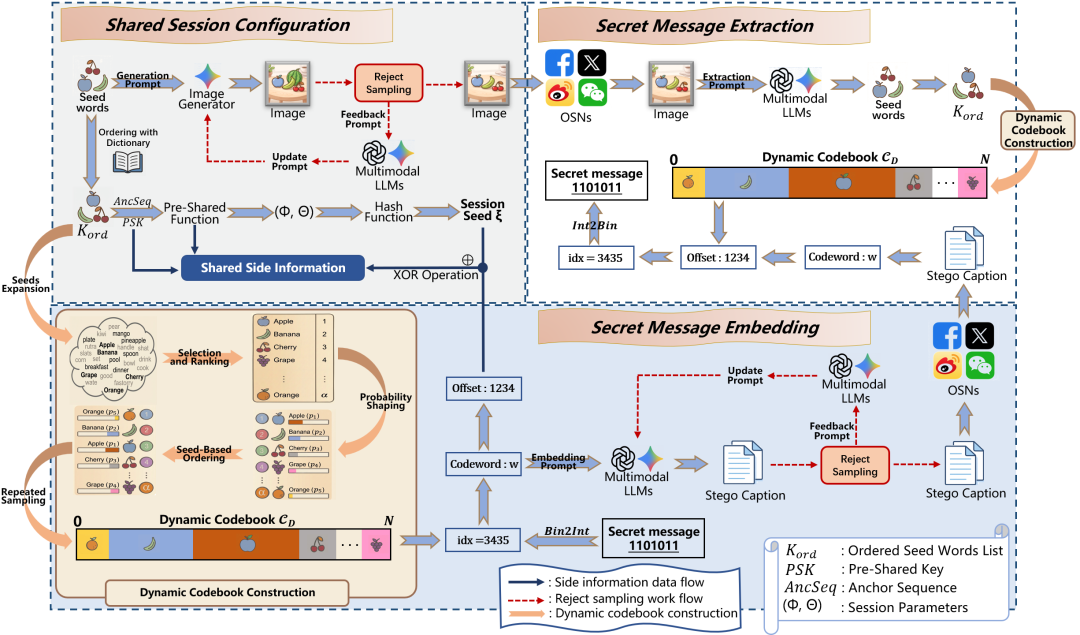
Text Steganography with Dynamic Codebook and Multimodal Large Language Model
作者:高健鑫、雷婼涵、彭万里
单位:中国农业大学
-
论文简介:该研究提出了一种基于动态码本与多模态大语言模型的黑盒文本隐写方法,首先通过多模态大语言模型构建动态码本,随后设计了加密隐写映射机制,确保秘密信息能够被准确提取。实验结果表明,所提方法取得最佳性能。
-
Paper链接:
https://arxiv.org/abs/2604.20269
-
Code链接:
https://github.com/CAU-ISS-Lab/Text-steganography


VOPE: Revisiting Hallucination of Vision-Language Models in Voluntary Imagination Task
作者:龙行明、张杰、山世光、陈熙霖
单位:中国科学院计算技术研究所
论文简介:视觉语言大模型(LVLMs)的幻觉研究大都集中在事实描述任务上,这些任务要求模型尽量忠实地描述图像内容。然而,很少有研究关注主动想象任务(如故事创作)中的幻觉问题。为此,我们提出了主动想象存在估计测评方法(Voluntary-imagined Object Presence Evaluation, VOPE)。具体而言,VOPE 基于LVLM主动想象的内容,设计存在性判断问题来评估模型对于自身生成内容的认知正确性,并以此识别主动想象幻觉。我们将 VOPE 应用于多种主流的LVLM,并得出了两个关键发现:1、大多数LVLM在主动想象过程中会出现严重的幻觉,且它们在针对自身想象内容的存在性评估中表现较差;2、现有幻觉消减方法在解决主动想象幻觉时效果有限,如何解决这一问题是未来研究的一个重要方向。
-
Paper链接:
https://arxiv.org/abs/2511.13420
-
Code链接:
https://github.com/qqwsad5/VOPE


AnyTrack: Unifying Visual Object Tracking with Any Modalities
作者及对应单位:李豪(陆军工程大学/大连理工大学)、诸葛云志(大连理工大学)、郝文宁(陆军工程大学)、张平平(大连理工大学)、张骁雄(国防科技大学)、王栋(大连理工大学)、卢湖川(大连理工大学)
论文简介:视觉目标跟踪旨在连续定位视频序列中的特定目标,其发展已从单模态方法演进至多模态融合范式。然而,现有的大多数多模态跟踪器通常针对固定的模态组合进行设计,不同输入组合需要部署独立的专用模型,这导致系统对模态缺失或模态质量退化场景的适应能力不足,且跨场景泛化性能受限。针对上述问题,本文提出了一种面向任意模态输入的统一目标跟踪框架AnyTrack。具体而言,我们设计了模态感知交互模块,通过动态交互机制桥接异构模态间的特征差异,并聚合时序线索以保持跨模态交互过程中的时空一致性。此外,我们引入了上下文理解模块,利用全局-局部提示建立视觉特征与目标位置之间的空间对应关系,通过目标感知的上下文建模增强前景-背景判别能力,从而实现精准定位。为支撑任意模态配置下的训练与测试,我们对现有主流多模态跟踪基准数据集进行了扩展,补充了灰度图像、语言描述及音频片段等模态信息。在完整模态与模态缺失两种设定下的大量实验表明,AnyTrack均取得了当前最优性能,充分验证了该框架的有效性与灵活性。
-
Paper链接:
https://github.com/IdolLab/AnyTrack
-
Code链接:
https://github.com/IdolLab/AnyTrack


Paths:Prompt-aware Spatial-temporal Transformer with Hierarchical Multi-modal Fusion for RGB-Event Video Person Re-Identification
作者:霍亚坤、王英权、刘扬扬、严天宇、诸葛云志、张平平、卢湖川 单位:大连理工大学
论文简介:RGB–事件视频行人重识别旨在利用RGB模态与事件模态之间的互补信息,在视野不重叠的摄像机之间检索特定行人。然而,现有方法通常分别对空间特征和时间特征进行建模,并且仅关注全局层面的多模态融合,导致所获得的特征表示不够理想。为解决上述问题,我们提出了一种新颖的时空多模态融合框架,称为 Paths。具体而言,我们首先引入记忆增强骨干网络,以提升单模态特征表示的鲁棒性。随后,我们提出提示感知时空Transformer,通过可学习提示在统一的Transformer架构中联合学习空间语义与时间信息。最后,我们设计了层次化多模态融合模块。该模块由全局图融合和局部Token融合两部分组成,旨在缩小模态差异并缓解局部空间错位问题。具体来说,前者利用动态图捕获粗粒度的上下文信息,后者则采用匈牙利匹配算法融合细粒度的局部Token特征。 借助上述模块,Paths能够学习适用于RE-VReID任务的鲁棒且具有判别性的特征表示。我们在EvReID、MARS和iLIDS-VID三个公开的RE-VReID基准数据集上进行了大量实验,实验结果验证了所提出方法的有效性。
-
Paper链接:
https://github.com/Reflection0427/Paths
-
Code链接:
https://github.com/Reflection0427/Paths


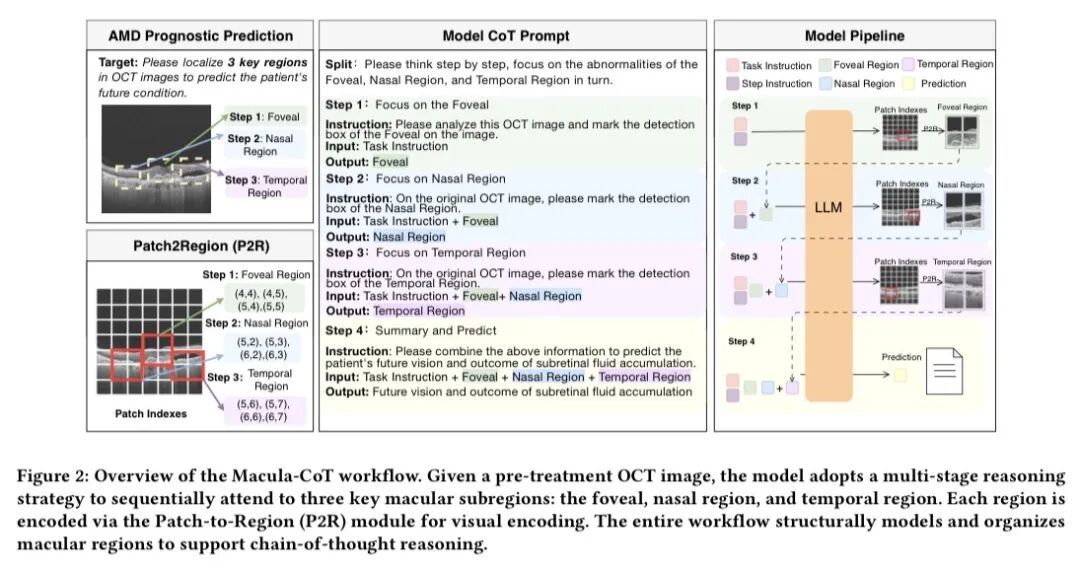
Macula-CoT: Macular Subregion-Aware Chain-of-Thought for AMD Prognostic Prediction
作者及对应单位:李欣月(北京工业大学)
论文简介:Recently, multimodal large language models (MLLMs) have exhibited strong potential in the automatic analysis of Optical Coherence Tomography (OCT) images, especially in predicting the progression of Age-related Macular Degeneration (AMD). However, despite their advanced visual-linguistic capabilities, they struggle with interpreting fine-grained OCT images that require specialized reasoning steps. To address this, we propose Macula-CoT, a macular subregion-aware chain-of-thought model for AMD prognostic prediction. By learning reasoning chains that align with the diagnostic process of ophthalmologist, it allows an accurate, transparent, and credible clinical reasoning. Specifically, we first introduce a multi-stage reasoning strategy that guides MLLMs to sequentially identify key macular anatomical subregions, thereby aggregating structured clues with fine-grained representations for disease prediction. Additionally, to ensure the understanding of detailed OCT macular regions, we propose a Patch-to-Region (P2R) module for visual encoding. It simplifies the encoding of irregular, complex macular patterns with explicit patch-level markers, enabling an effective perception and discrimination of local regions. In this way, various macular regions can be seamlessly modeled and captured in a structured manner, providing enriched contexts for disease prediction and interpretable reasoning chains for clinical reference. We evaluate Macula-CoT on two AMD prognosis datasets, achieving SOTA performance in both accuracy and interpretability for subretinal fluid absorption and visual acuity improvement prediction. The code will be publicly available.


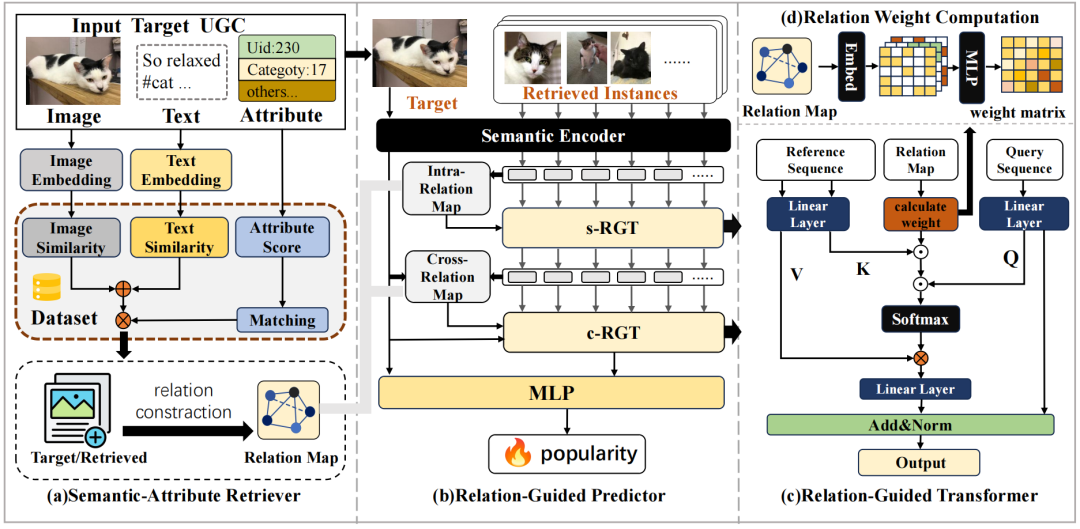
Enhancing Relation Modeling with Social Attributes for Social Media Popularity Prediction
作者及对应单位:郑博仑(杭州电子科技大学)
论文简介:We propose a Relationship-Enhanced Retrieval-Augmented Framework (RE-Rag) for media popularity prediction. Its core idea is to model relative relationships among UGCs from a dual-factor perspective, considering both content quality and distribution mechanism, and incorporate them into the retrieval and prediction process to effectively leverage valuable historical instances. This enhances the accuracy and generalization capability of popularity predictions. Extensive experiments on three real-world datasets validate the effectiveness and superior performance of this approach.
-
Paper链接:
http://arxiv.org/abs/2607.19200
-
Code链接:
https://github.com/BBEC-opt/RE_RAG


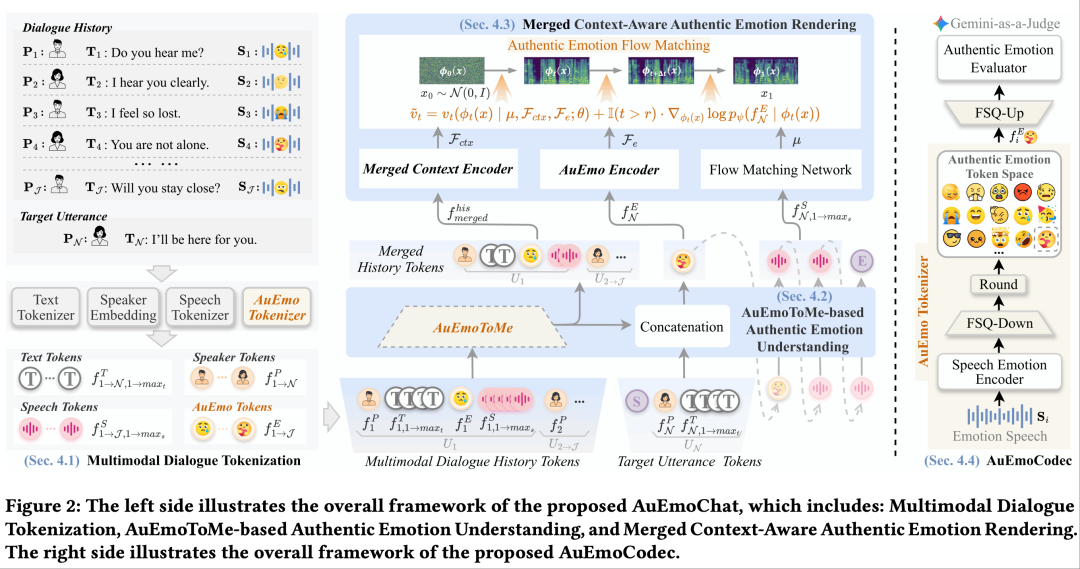
Authentic Emotion Understanding and Rendering for Conversational Speech Synthesis
作者及对应单位:贾真琦(内蒙古大学)、赵源(内蒙古大学)、阿如汗(内蒙古大学)、刘瑞(内蒙古大学)、李海洲(香港中文大学,深圳)
-
论文简介:本文提出真实情感理解与渲染的对话语音合成框架AuEmoChat,通过AuEmoCodec学习真实情感表示,并利用AuEmoToMe合并情感信息冗余的多模态上下文Token,结合自回归建模与流匹配生成,实现准确的上下文理解和自然、真实的情感表达。
-
Paper链接:
https://arxiv.org/abs/2607.15755
-
Code链接:
https://github.com/AI-S2-Lab/AuEmoChat


EmoCtrl: Controllable Emotional Image Content Generation
作者:杨景媛、骆伟斌、黄惠
-
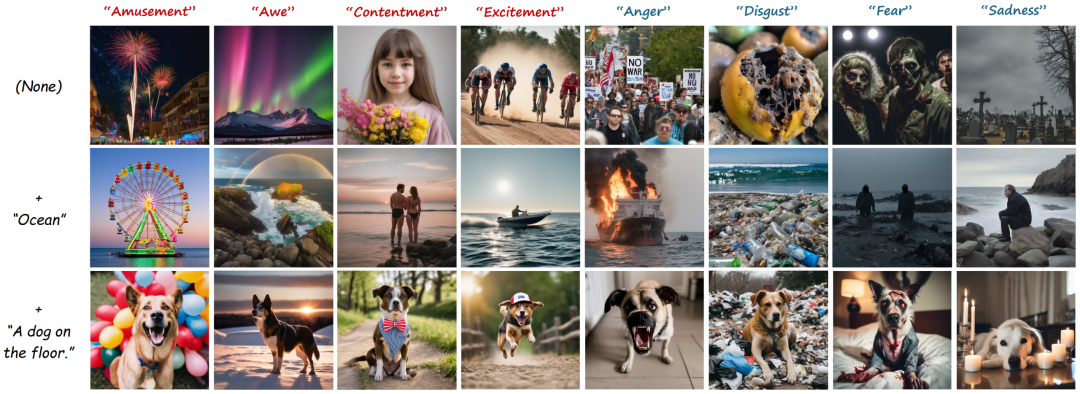
论文简介:本文引入了可控情感图像生成(C-EICG)任务,并提出EmoCtrl,分别通过内容语义和感知线索在文本和视觉层面丰富情感表达。为了与人类偏好保持一致,进一步设计情感奖励和情感驱动的偏好优化策略。
-
Paper链接:
https://arxiv.org/pdf/2512.22437
-
Code链接:
https://github.com/JingyuanYY/EmoCtrl


CLID-Gait: Clinically-Inspired Representation Learning for Depression Recognition from Gait
作者:高若一、李瑾熠、赵筱瑜、刘竞宇、董群喜、胡斌 单位:北京理工大学
论文简介:本研究面向步态抑郁识别,提出一种临床启发的图表示学习框架。该方法将症状相关先验融入学习过程,通过关节重要性建模和平衡感知拓扑结构捕捉抑郁相关步态特征,并利用大规模动作数据迁移学习缓解高质量临床标注数据不足的问题。
-
Paper链接:
https://openreview.net/pdf?id=MyzjIx77nv

